

Framework overview: why a matrix matters
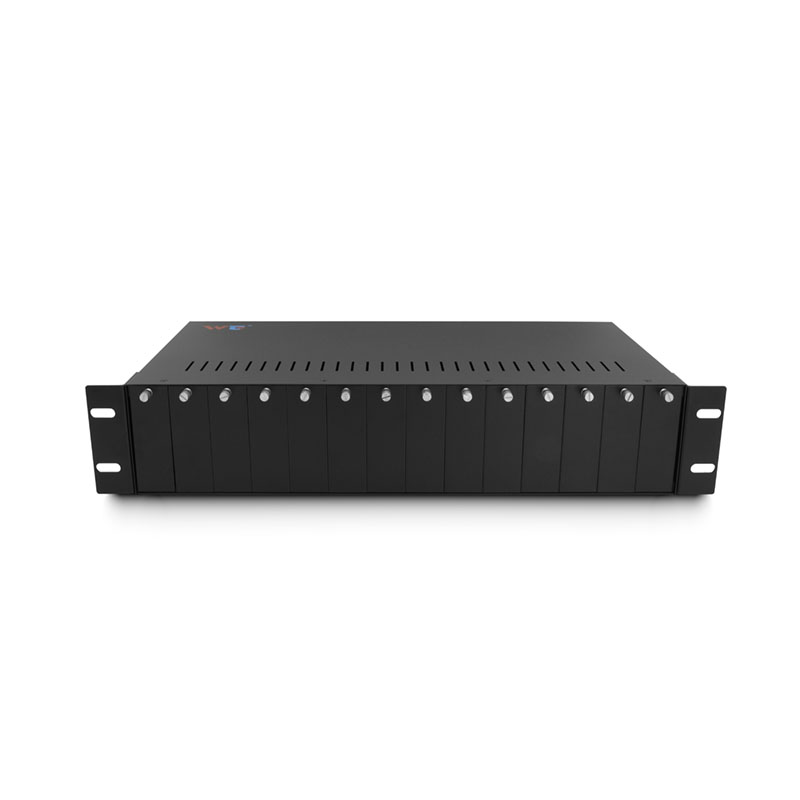
Organising a transceiver fleet requires a repeatable structure that engineers can rely upon. The matrix I propose maps procurement, lab validation, deployment and lifecycle replacement against cost, performance and compatibility. For teams that also source media conversion gear, consult leading media converters manufacturers early in the procurement phase to align link budgets and physical interfaces. This framework applies directly to QSFP28 SR4 modules used over multimode fiber in dense campus and data-centre links and helps codify decisions about optical transceiver inventory.
Inventory and classification
Begin by classifying every unit by type (QSFP28 SR4, spare SFP28 uplinks), vendor, date code and optical budget. Record multimode fiber type (OM3/OM4) and connector format (MPO/MTP). Use a simple tag convention so technicians can identify a transceiver’s approved link distance and wavelength without consulting a server—this reduces human error during hot-swap operations and simplifies capacity planning.
Lab validation and operational teardown
Before fleet-wide roll-out, each vendor lot must pass a compact validation suite: BER stress at target data rates, temperature cycling across the expected rack environment, and end-to-end insertion loss checks with representative patching. When you perform an operational production teardown, include {main_keyword} and {variation_keyword} checks in the procedure so that diagnostics map to the real installation. Keep test logs attached to serial numbers; this is the evidence that justifies warranty claims and retirement decisions.
Deployment, monitoring and enforcement
Deployment should be governed by the matrix: assign approved transceiver types to specific link classes and enforce via inventory-controlled staging. Monitor link statistics—CRC errors, Rx/Tx power levels and lane skew—through the switch OS and correlate anomalies with recent swaps. Where practical, automate alerts for rising LR power variance; this often precedes a failed channel and reduces Mean Time To Repair. Integrate occasional physical audits in high-density sites such as London’s Docklands data centres to verify that documented cabling matches installed MPO pinouts.
Common mistakes and alternative approaches
Teams often skip vendor lot testing to save time and then encounter mismatch—incorrect MPO polarity or a lower-than-expected optical budget. Another widespread error is assuming vendor interchangeability without checking lane count: SR4 is fundamentally a four-lane optical module and cannot simply replace a single-lane SFP28 without architecture changes. Alternatives include standardising on transceiver families from two vetted vendors to avoid single-supplier risk, or adopting media conversion at rack edge—using trusted fiber media converter manufacturers—when you need optical-to-copper transitions for legacy switches.
Operational controls and sustainment — short checklist
Maintain: inventory database with serial-level test results; staging policy that enforces lot traceability; scheduled replacements tied to manufacturer MTBF estimates; and a push for firmware alignment across switch platforms. Use physical lab rigs to replicate problematic failure modes—signal skew, connector contamination—and develop a repair SOP that technicians can execute in under an hour. A simple checklist reduces variability and protects service-level commitments.
Advisory: three golden rules for selection and governance
1. Measure first, buy second: validate compatibility against the actual MMF infrastructure and switch optics before committing to a single vendor lot. Accurate insertion loss measurements and knowledge of OM3/OM4 type will prevent costly returns.
2. Standardise test coverage: require BER, temperature and optical power hysteresis tests for each new lot; ensure records tie to serial numbers for warranty leverage.
3. Enforce placement by policy: map approved transceiver classes to link tiers (aggregation, spine, leaf) and prevent ad-hoc swaps via inventory-controlled staging and technician sign-off—this keeps support predictable and reduces incident volume.
These rules translate into fewer emergency rollouts, clearer replacement budgeting and a demonstrable chain of custody for every optical transceiver. For operational teams, the result is smoother maintenance and faster fault resolution—real value shown at sites such as the London Docklands where dense cabling and high throughput magnify mistakes. WINTOP. —