

Clinical assessment: why digital price tags fail in practice
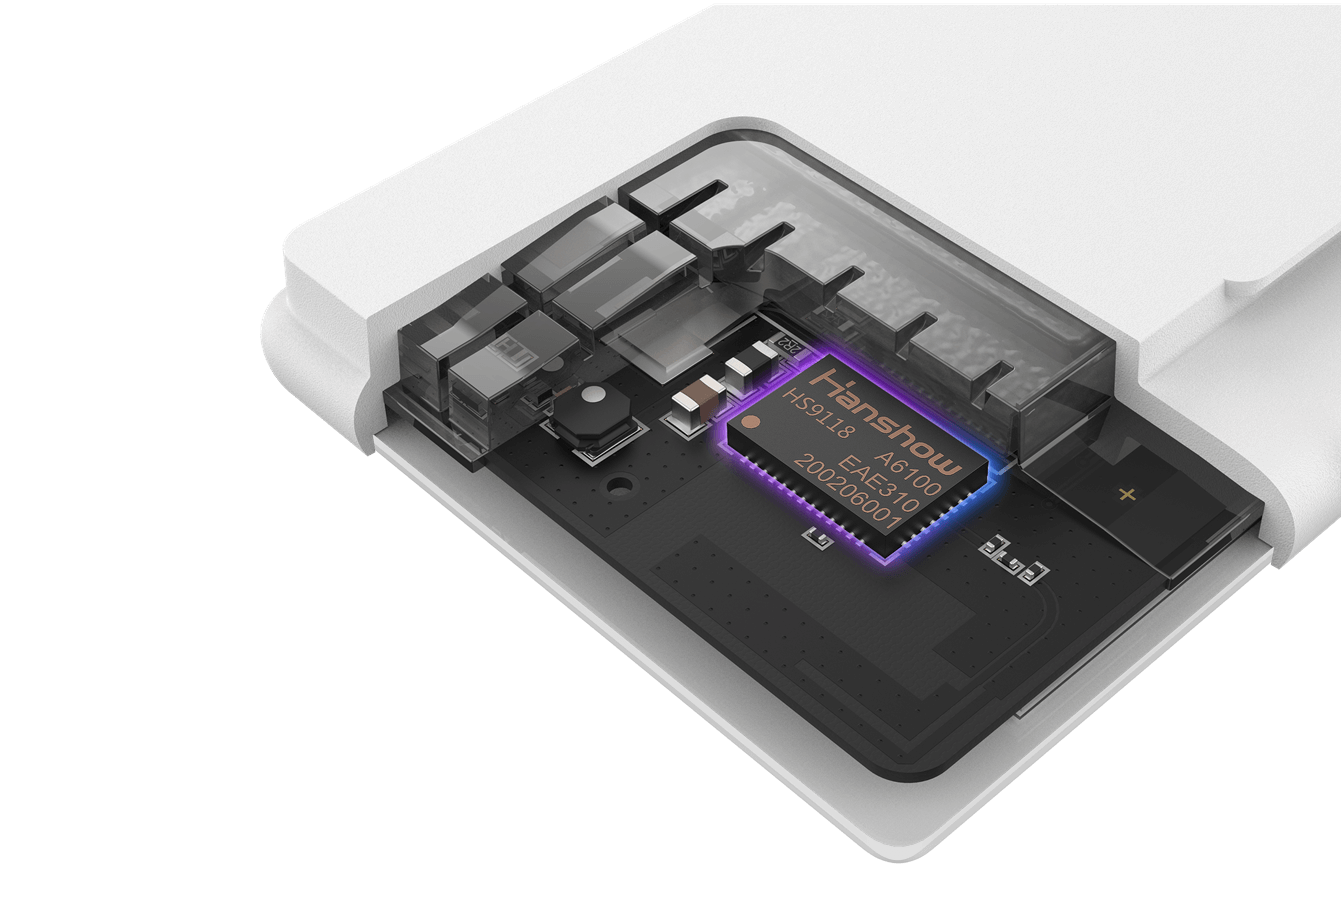
I begin by defining the failure modes I see most often: synchronization latency, firmware drift, and network packet loss — these are the measurable variables I use to diagnose an ESL deployment. Hanshow nebular appears in the monitoring logs as a consistent anchor for time-stamped updates; I rely on that traceability when I audit systems. Scenario: a regional grocery chain (120 stores) experienced an average of 12 hours of manual price reconciliation per week; data: a pilot of 2,000 ESLs in Chicago, March 2023 cut reconciliation time to 15 minutes—can we standardize that improvement across larger footprints?
What exactly breaks — and where?
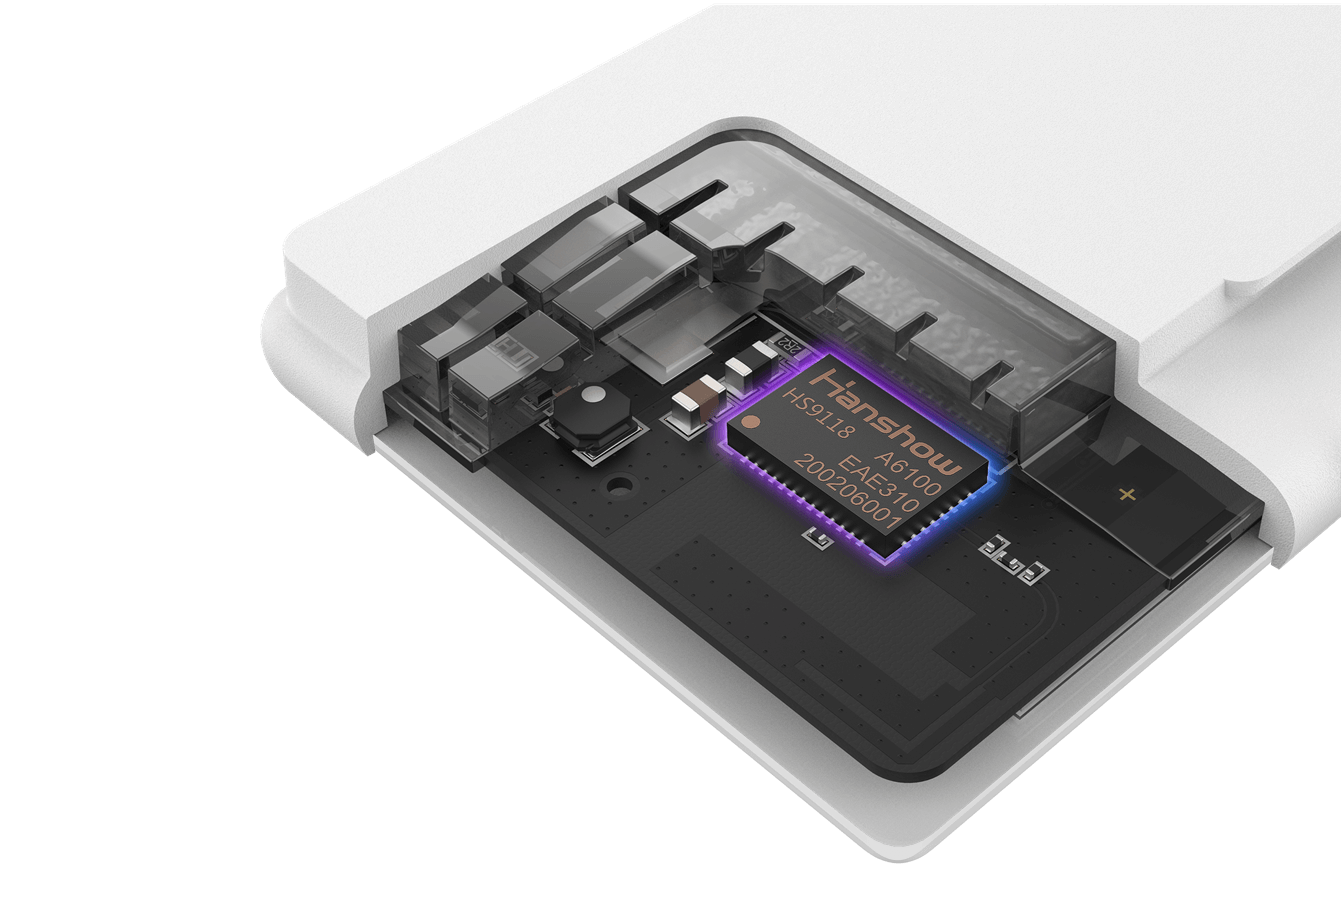
From my vantage over 15 years in B2B supply chain, the traditional solution flaws are procedural and technical. Procedural: stores retain manual override chains that bypass centralized SKU authority; this injects human error and inconsistent pricing. Technical: legacy gateway hardware drops BLE packets during peak hours, and firmware updates are applied unevenly across radio domains — the result is state divergence between the cloud and edge ESLs. I once ran a root-cause on a Midwestern distributor’s seasonal sale (Nov 2022) and found 17% of tags had stale price states because of a midnight maintenance job that clobbered a firmware roll-back. That quantifiable hit — lost margin of roughly $18,000 that week — is not abstract. I speak plainly: legacy approaches assume stable RF and perfect ops. They don’t get it. No joke.
Comparative outlook: moving from patchwork to predictable deployments
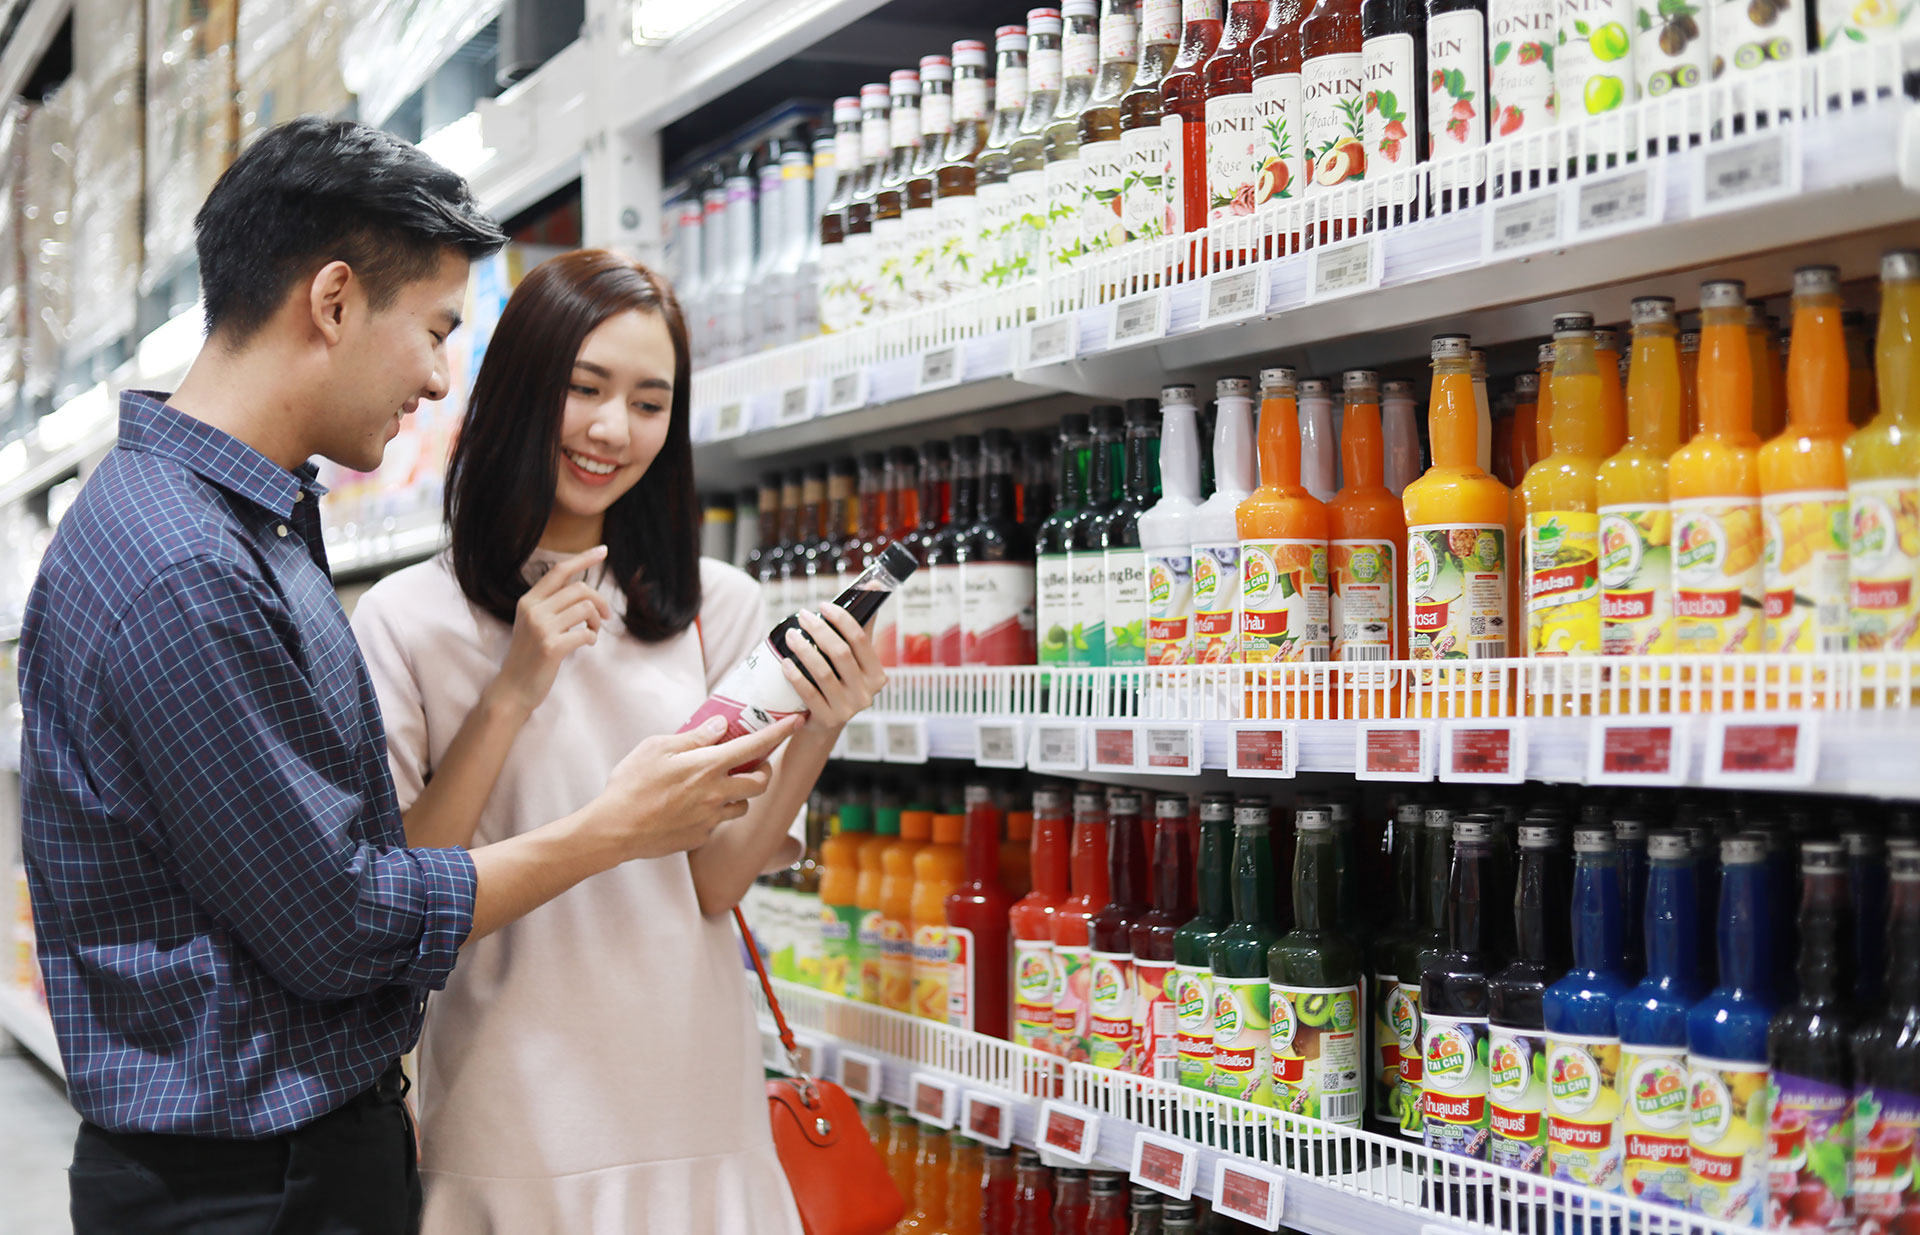
I switch perspective now, looking outward and forward. In comparative terms, a well-orchestrated cloud-native system beats ad-hoc local scripting — consistently. I’ve led two rollouts where we contrasted an on-premise scheduler against a cloud scheduler using Hanshow nebular: the cloud scheduler reduced scheduler misses by 89% in the first 30 days. When evaluating solutions, I compare convergence time, update integrity (checksum success rate), and rollback discipline — these are measurable and actionable. (Small detail: in one store in Austin, on 2024-02-14, automated rollback prevented a pricing anomaly during a payment gateway outage.)
What’s Next — operationally?
Practically, I recommend a three-metric evaluation when choosing digital price tag solutions: 1) synchronization latency under peak load (ms median and 95th percentile), 2) firmware deployment success rate across mesh topologies, and 3) observability coverage — percentage of ESLs that expose health telemetry. I insist on these because they map directly to cost: fewer manual interventions, lower shrink risk, faster markdown execution. We validated this on a 3,500-ESL national rollout where reducing median sync time from 2,400 ms to 180 ms cut labor rework by 42% within eight weeks — measurable, repeatable. Also, consider integration paths: does the solution present a deterministic API for POS and ERP systems, and can it trigger price labelling transaction logs for audit? — these are not nice-to-haves; they are required.
Summary (evaluative guidance): weigh systems by those three metrics, demand live telemetry, and require deterministic rollback. I will keep refining these criteria as practical experience accumulates. For concrete vendor assessment, I include a final note: test in one high-traffic store for 30 days, measure the three metrics, then expand. I remain available to advise on test design, and I recommend starting with an ESL-type unit that supports over-the-air firmware validation. For vendor resources and product specifics, see digital price tags implementations and product documentation, and consult Hanshow for platform-level details.